1. Model introduction
Wan2.2-T2V-A14B is a text-to-video model with a dual-expert MoE DiT: a high-noise expert (transformer) denoises timesteps t ≥ boundary and a low-noise expert
(transformer_2) handles the rest. Conditioning comes from a UMT5 text encoder; latents go through the Wan VAE (4×
temporal compression).
Key highlights for RL training:
- Two experts, one boundary.
boundary_ratio = 0.875— which expert a train pair updates depends only on its timestep. Single- and dual-expert training are both supported:--update-weight-target-modulenames the experts to load, train, and sync. - Two guidance scales. Rollout denoises low-noise steps with
guidance_scale_2. Left unset, the engine silently substitutes its own default (the model’s sampling config, elseguidance_scale), which the trainer cannot see — so training asserts--diffusion-guidance-scale-2is set explicitly, because a silent mismatch against rollout would corrupt the ratio. - USP-ready. Wan was enabled for Ulysses × Ring sequence parallelism.
2. Supported variants
3. Family config
Registered inmiles/backends/fsdp_utils/configs/wan2_2.py:
4. Launch
4.1 Flow-GRPO + PickScore (4 train GPUs + 1 reward GPU)
Canonical recipe:scripts/run_diffusion_grpo_wan22_pickscore_5gpu.py
Status: ○ NV — Not verified
4.2 Full-finetune Flow-GRPO + PickScore, multi-node (2×8 train GPUs + 1 reward GPU)
Recipe:scripts/run_diffusion_grpo_wan22_pickscore_17gpu_multinode.py
(full finetune, no LoRA, true on-policy). Start the
multi-node Ray cluster, then run on the head node:
Status: 🧩 PG — Proxy gated
--four-gpu-ci scales the recipe to one 4-GPU node for e2e CI.
4.3 LoRA SFT on (video, prompt) pairs (4 GPUs, no rollout engines)
Recipe:scripts/run_diffusion_sft_wan22.py
Status: ○ NV — Not verified
{"prompt": "...", "target": {"visual": "/abs/path.mp4"}}. Prepare the videos offline: each must
already be 832×480 with square pixels and exactly 161 frames (81 frames at --sft-frame-stride 2). The encoder
rejects any other video rather than resizing or trimming it.
5. Reference results
5.1 17-GPU multi-node full-finetune GRPO
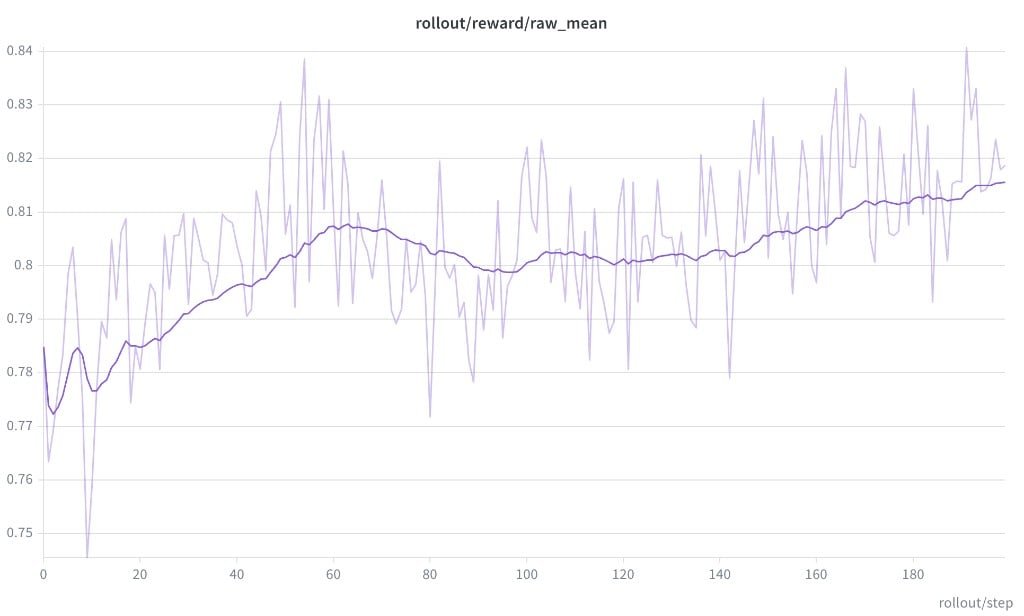
CFG enabled (4.0/3.0)
train/model_output_mean_abs_diff: 0.0 every rollout.rollout/reward/raw_mean: ~0.77 → ~0.82.- Final
eval/pickscore_test: 0.8231 (rollout 199, 28 denoising steps—not 40, UniPC, 2048 prompts).
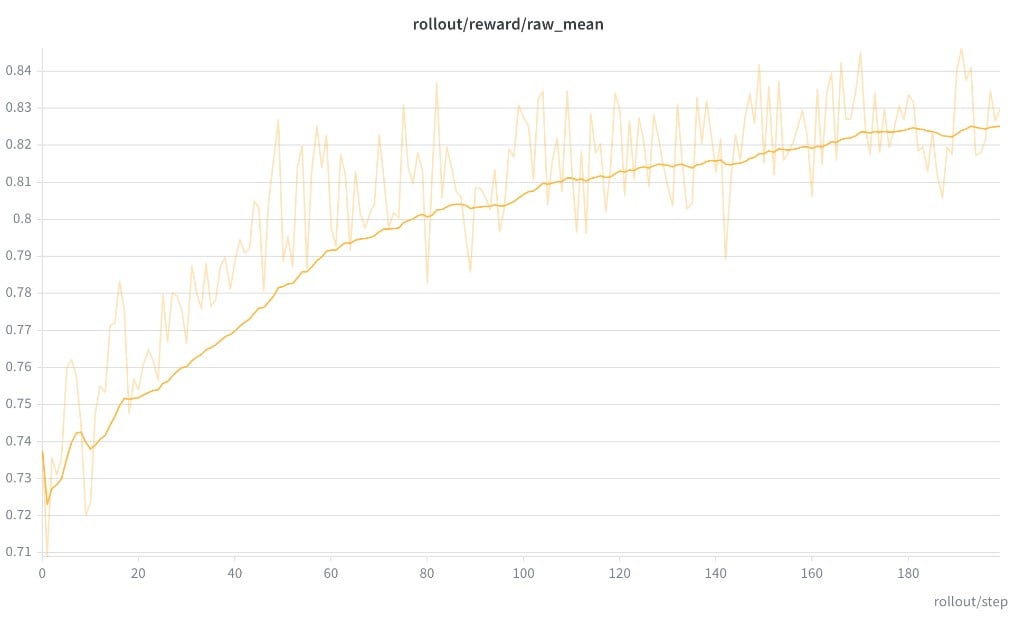
CFG disabled (1.0/1.0)
rollout/reward/raw_mean: ~0.72 → ~0.83.- Final
eval/pickscore_test: 0.8243 (rollout 199, 28 denoising steps—not 40, UniPC, 2048 prompts).
6. Pairs well with
- Single-Prompt Multi-Generation — the microgroup mechanics behind
--rollout-microgroup-size 8. - LoRA Training and Weight Sync — IPC merge used by the GRPO recipe.
- SDE Step Backend — how the trained SDE step is scored train-side.
- Rewards — PickScore worker pool configuration.