--update-weight-transfer-mode p2p, miles enables more efficient weight transfer from training ranks to rollout engine ranks. More details on the design and implementation can be found in this issue.
Usage
To enable P2P weight transfer, add the following flag to your training command:--sglang-remote-instance-weight-loader-start-seed-via-transfer-engine, and the writes go over Mooncake. To write over NIXL instead, add --p2p-transport nixl and start the rollout engines with --sglang-remote-instance-weight-loader-start-seed-via-nixl. SGLANG_REMOTE_INSTANCE_NIXL_BACKEND picks the NIXL plugin on both sides (default UCX).
How It Works
The default weight transfer mode in miles isbroadcast: after training, updated weights are broadcast via NCCL to all rollout engine ranks. This works but does not fully utilize the available bandwidth, as redundant copies of the same weights are transferred to multiple ranks.
P2P mode addresses this by having each training rank transfer only the specific weight shards required by its target rollout engine rank(s), writing them directly to remote memory without redundant copies. The key steps are:
-
Initialization: Training ranks establish point-to-point connections (via RDMA) to their target rollout engine ranks. Including:
- Create a transfer plan that maps each training rank to its target rollout rank(s) based on GPU counts and parallelism configuration.
- Query remote rollout engines for their weight memory registration info (addresses and sizes for RDMA writes).
- Query each target rank’s parallelism config and server args, and build a model replica of its sharding layout without parameter storage, which converts HF weights into the exact bytes that rank’s loader would write.
- Weight gather: Megatron TP/EP shards are all-gathered and converted to HF format, same as the broadcast path.
- P2P transfer: Instead of a collective broadcast, each source rank writes bucketed weight tensors directly to the destination rollout rank’s memory, in a write-only fashion.
- Synchronization: Once all RDMA writes are confirmed complete, rollout engines increment their weight version and resume generation for the next training step.
Architecture
Both broadcast and P2P modes share the same bucketed weight-update pipeline inmiles/backends/megatron_utils/update_weight/. The diagram below shows which components are shared and which are P2P-specific.
Shared components (broadcast & P2P)
P2P-specific components
The model replica runs the rollout engine’s own sglang code in the trainer process: its model construction, startup postprocess and weight loaders. The trainer and the rollout engines therefore run the same sglang build, and their GPUs share an architecture: postprocess chooses kernels and layouts by architecture (TRT-LLM MoE layouts and UE8M0 scales on Blackwell, for example), so a replica on a Hopper trainer would lay out bytes for Hopper while Blackwell engines expect their own.
Supported Model Architectures
P2P derives HF-to-parameter mappings by probing each replica’sload_weights at the first update (protocols/utils/loader_probe.py). The probe uses real GPU inputs and meta parameters, then caches the mapping for later updates. Models need no separate mapping implementation.
P2P writes parameters only. The engine recomputes derived buffers, such as Gemma norm’s weight + 1, after the update; --check-weight-update-equal checks those buffers too.
The following sglang model classes are tested:
Note: All the above models are tested on H100-80GB clusters. For Kimi-K2, we settraining nodes = inference nodes = 32to ensure sufficient memory. The original Kimi-K2 checkpoint uses a block-quant size of[128, 128], which will trigger errors ifsglang-tp-size = 32. To work around this, we re-quantize to[64, 64]and update all affected scale tensors accordingly.
Validated Models
All models below have been validated with--check-weight-update-equal in P2P mode.
Enabling--check-weight-update-equalfor Kimi-K2 is non-trivial due to several issues:We verified P2P correctness for Kimi-K2 by enabling
- The user must first dequantize the Kimi-K2 model to BF16 for training, then re-quantize the parameters for weight updating. Meanwhile, the rollout side snapshots the original Kimi-K2 tensors as the reference when enabling
--check-weight-update-equal. This means the rollout SGLang engine should load the checkpoints processed by thedequant-requantpipeline.- We use modified checkpoints with block-quant size
[64, 64], so anyquant/dequantcode that hard-codes the block-quant size as[128, 128]will break.- Certain tensors that are only initialized on the rollout side (e.g.,
k_scale/v_scale) must be skipped during the weight-check process.--check-weight-update-equalwith hard-coded workarounds for the issues above. The transferred weights were confirmed correct. These hard-coded workarounds are verification-only and will not be merged into the main branch to keep the codebase maintainable.
Profiling Results
For M source ranks and N target ranks, with source pp sizesrc_pp and target ep size sgl_ep, the benefit of P2P transfer is approximately:
- utilizes
M // src_pptimes more source transmission bandwidth. - each target rank receives
sgl_eptimes less data.
pause_generation call returns and before update_weight call exits to exclude request queue abortion time.
Table includes steady-state steps 3–12 average. For Kimi-K2, the RDMA (ms) column includes GPU-side post-processing time (post_load_weights ~884ms) since this model requires GPU-side weight requantization after RDMA transfer.
Models marked with ★ are MoE architectures, where P2P benefits are most pronounced due to expert-parallel sharding reducing per-target transfer volume.
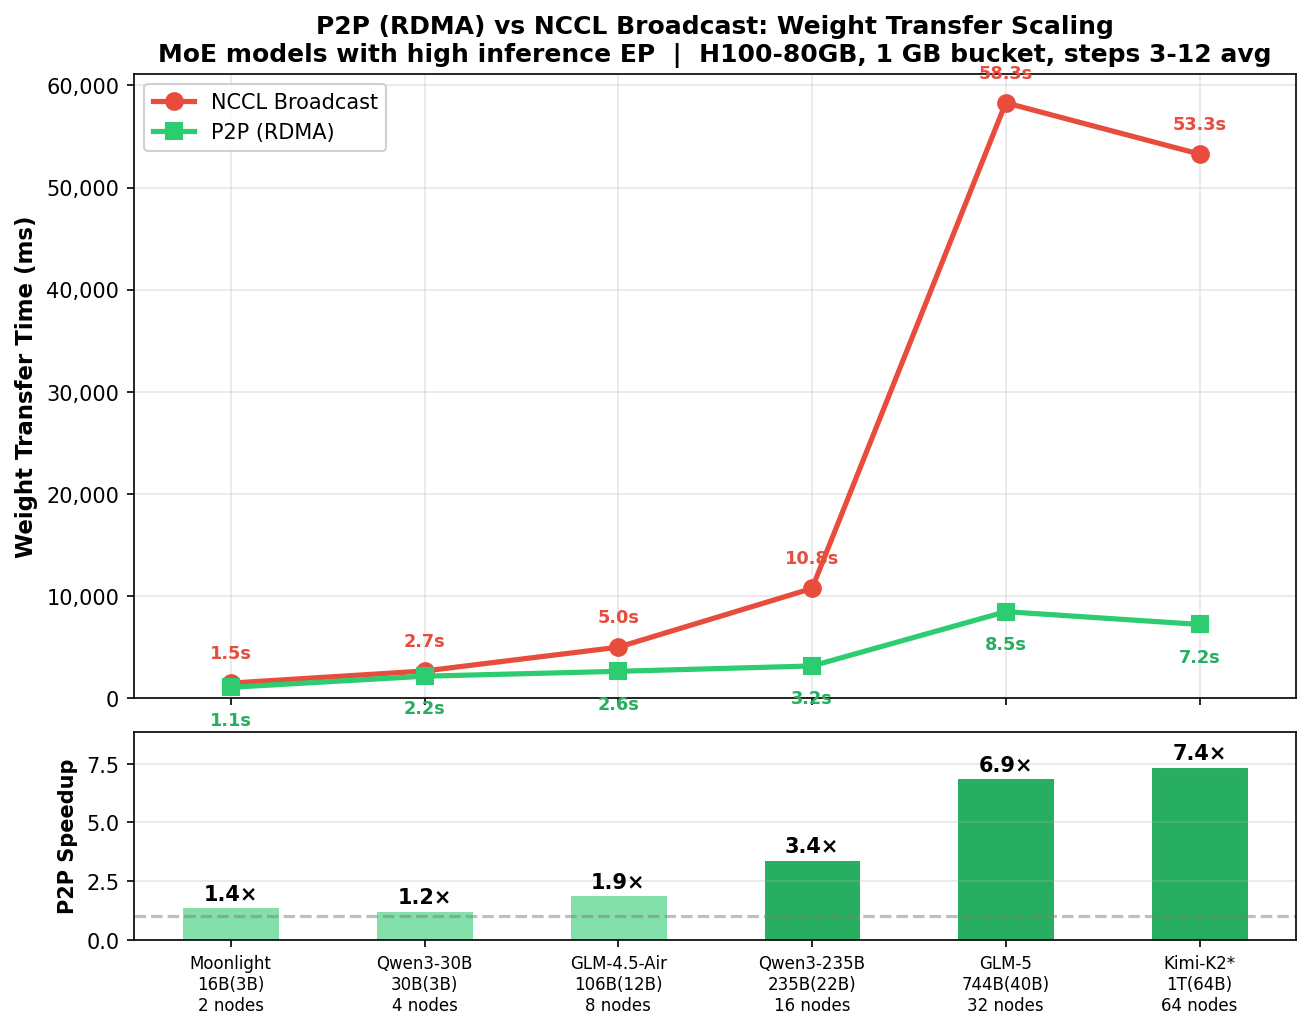
post_load_weights requantization on rollout engines.
Examples
CI Test (single-node, Qwen3-4B)
The P2P weight transfer E2E test validates correctness on a single node usingQwen3-4B: